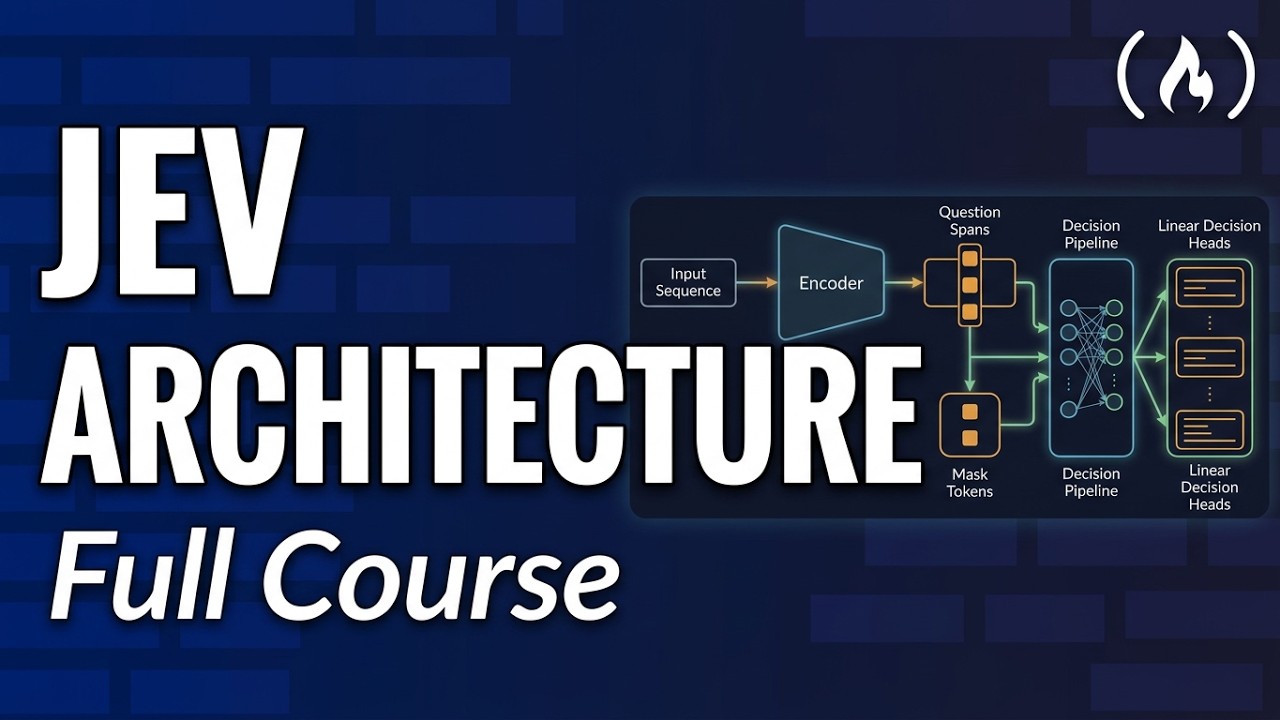
Jev Course – Prefill-Only Inference & Decision Models from Scratch
Title history
- Jev Course – Prefill-Only Inference & Decision Models from Scratch — observed on 20261027-1319 UTC (YouTube)
Keywords
Summary
155 words
Critical Evaluation
Value of the Information & Strength of the Argument
The video provides high practical value by demonstrating a novel inference paradigm (Jev) that replaces conventional text generation with structured decision outputs, significantly reducing latency and improving predictability. The argumentation is methodical: it starts with a concrete baseline showing the inefficiency of token-by-token decoding, then builds progressively from encoder to decoder architectures, each time explaining the rationale behind design choices such as question-first ordering and mask tokens. The coding examples are thorough and encourage hands-on learning. The instructor justifies each step with technical reasoning, such as why positional attention favors question-first ordering in encoders, and why bidirectional attention prevents caching in that setup. The final comparison between encoder and decoder trade-offs is nuanced, giving clear guidance for architecture selection. The overall argument is coherent and well-supported, though it assumes a strong technical background, which reinforces its value for an advanced audience.
Scientific Rigor, Source Quality, Title Accuracy
The scientific rigor is high: the instructor is an established author (Manning publication) and the content is explicitly based on first principles, with code available on GitHub. The sources cited include the official repository and a reference to the author’s book on quantization and fast inference, adding credibility. No external claims are made without being traceable to the implementation. The title precisely reflects the content—this is a course on Jev and prefill-only inference—and there is no discrepancy between the advertised topic and the presented material. The presence of a sponsor mention (Scrimba) is noted but does not affect the technical quality, as it is clearly separated from the instructional content. No discrepancies were found between the title and the actual content; the video matches its description thoroughly.
283 words
Title / Content Match
The title accurately describes the content: a comprehensive course on Jev-style decision models and prefill-only inference.
Quality & Reliability
9/10
Expert instructor with a Manning publication, reputable freeCodeCamp channel, detailed code implementation, and clear explanation of advanced technical concepts.
Key Moments
Markers derived by PSI from the transcript: the creator did not define chapters.
- Introduction to Jev and the difference between prefill and decode stages.
- Baseline: vanilla LLM token-by-token decoding, illustrating the latency of autoregressive generation.
- Encoder-only architecture for fast decisions, explaining the question-first ordering and mask tokens.
- Decoder-only architecture and context caching, with custom causal attention masking for multi-question packing.
- Extracting decision point logits and token probabilities, addressing multi-token collision issues.
Cited Sources
- Jev Course Repository (GitHub) — Provides all code referenced in the course, enabling hands-on practice.
- Quantization and Fast Inference (Manning) — Author's book, a deeper reference on inference optimization.
- freeCodeCamp News — Platform hosting articles and tutorials related to programming and AI.
- freeCodeCamp Main Site — General freeCodeCamp resource for learning to code.
External References
Contribution & Novelties
The video fills a gap by providing a step-by-step practical implementation of Jev-style decision models, a topic rarely covered in beginner or intermediate resources. It uniquely combines encoder and decoder designs with custom attention masking and KV-cache reuse, and ties together subtle training techniques like RLCD. The original contribution lies in breaking down a complex inference paradigm into digestible coding exercises, making it accessible to those with a solid ML background yet no prior exposure to prefill-only decision models.
Pour aller plus loin :
- KV Cache in Transformer Inference — Reference paper on KV-cache optimization, highly relevant to the caching discussions.
- BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding — The encoder architecture tutorial uses BERT as a backbone.
- GRPO: Group Relative Policy Optimization — Paper on the reinforcement learning method used in the course.
- RLCD: Reinforcement Learning for Calibrated Decisions — Direct reference for the RLCD loss function, closely tied to the course’s final topic.
157 words
Radar Profile
The radar profile is heavily skewed toward technical depth and information quantity, reflecting a focused and comprehensive tutorial. The moderate scores on reliability are likely due to the lack of independent verification, but the expert author and reputable channel mitigate this. The overall shape indicates a resource that prioritizes technical proficiency and practical utility.